11 min read
You've got Kubernetes, MLflow, and SageMaker in a Skills block, but Experience still reads "worked on machine learning projects" with no pipeline names. US parsers won't treat a Skills dump like dated production lines. Without orchestration and monitoring terms in Experience, qualified MLOps files stall before a human opens them.
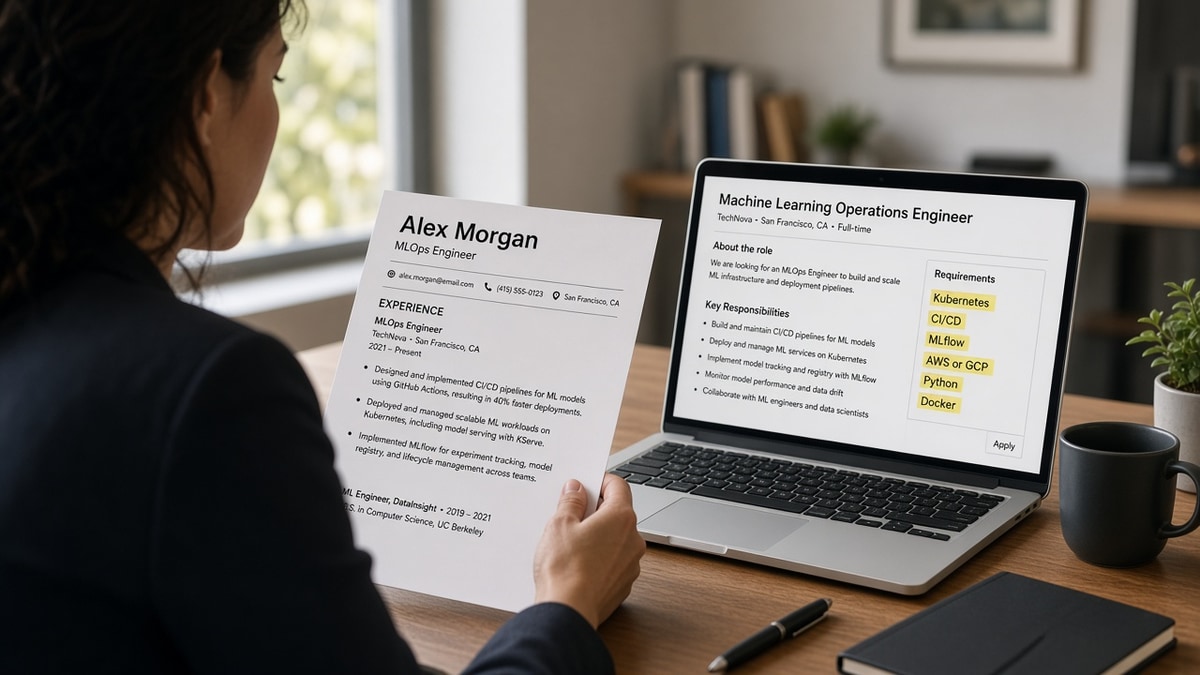
This page is an MLOps resume keywords US ATS list you'll actually use: pull terms from the posting, place them in the bullet where you shipped or monitored models, and keep Skills as backup, not the main store. It's not a paste-all cloud. Before you rewrite, check your resume for free with the job description pasted in so you see whether Experience or Skills is carrying CI/CD and deployment tokens today.
Layoff season in ML platform teams hits fast, and you're tailoring ten reqs a night. You don't need another generic keyword cloud. You need five placement steps, before/after lines, and a copy-paste bullet bank that matches how Greenhouse and Workday display your file after upload. When the posting asks for a letter, generate a cover letter so the opening line names the same deployment terms sitting in bullet one.
I've screened enough MLOps stacks in Workday to know one sharp Kubernetes deploy bullet beats fifteen platform names in a Skills column. Below you'll map posting language to real production work, fix the mistakes that make parsers miss model monitoring terms, and run a final parse check before you hit submit.
Quick Wins
- Highlight six to eight terms from the posting before you touch your resume file.
- Put the primary MLOps keyword in the first eight words of bullet one under your current role.
- Move notebook-only work to Projects until you have a production deploy story in Experience.
- Mirror the posting spelling: MLflow versus ML Flow, SageMaker versus AWS ML.
Why parsers weight production bullets over your Skills cloud
An MLOps resume keywords US ATS list only works when terms land where parsers and humans look first. Corporate ATS exports show Experience as dated lines with employer, title, and bullets. Skills often parse as a flat comma list with no dates and less context. Recruiters scanning an MLOps req in Greenhouse scroll Experience before they expand Skills.
The Skills section is a mirror, not the engine. It can repeat Kubernetes and MLflow after you proved them in bullets. When Skills carries fifteen platforms and Experience says "built ML solutions," the file fails the five-second skim even if the parser captured every token.
MLOps reqs blend data science and platform engineering language. Postings repeat a small set: model deployment, CI/CD, container orchestration, experiment tracking, monitoring, and a cloud ML service. The bank below is a map against the ad, not a paste-all checklist. Your posting wins.
- Core: MLOps, machine learning operations, model deployment, model serving
- Orchestration: Kubernetes, Docker, Kubeflow, Airflow, Argo Workflows
- Tracking and registry: MLflow, Weights and Biases, model registry, feature store
- Cloud ML: AWS SageMaker, Azure Machine Learning, Vertex AI, Databricks
- Monitoring: model drift, Prometheus, Grafana, data quality checks, A/B testing
- Pipeline: CI/CD, GitHub Actions, Jenkins, Terraform, Infrastructure as Code
Keyword stuffing in Skills also creates mismatch risk. You list Spark, Kafka, and Feast next to TensorFlow without a bullet that names the integration. Phone screeners ask which release used each tool. Empty Skills lines are easier to defend than inflated ones.
If your bullets still read weak after keyword placement, read why weak bullet points get ignored before you add more platform names. Keywords without scope and outcome still die in the skim.
Five steps to place MLOps resume keywords for US ATS
Work one posting at a time. These five steps take about twenty minutes per tailored version once you have a base file in single-column PDF or DOCX.
Step 1: Pull must-have terms from the job description
Open the posting and highlight every MLOps-related requirement: orchestration stack, cloud ML service, monitoring tooling, and framework names. Copy the exact spelling. If the ad says SageMaker twelve times and never AWS ML, match SageMaker in your bullets.
Before: Skills block lists Kubernetes, MLflow, Terraform, PyTorch, Spark, Kafka, and Grafana with no posting reference.
After: Scratch pad lists model deployment, SageMaker, CI/CD, drift monitoring, and MLflow because those five appear in the must-have paragraph.
Step 2: Assign each keyword to a production role or project
Draw a line from each highlighted term to where you used it in production or a paid contract. Notebook experiments count only under Projects unless they shipped. If you cannot name the release, the term stays off the resume until you have an honest bullet.
Before: Kubeflow on Skills with no employer bullet mentioning pipelines or serving endpoints.
After: Kubeflow moves to a bullet under Platform Co: "Built Kubeflow pipelines for weekly retraining on fraud models, cutting manual notebook handoffs across three data science pods."
Step 3: Rewrite bullet one under your current job
The first bullet under your latest title gets the most skim time. Put the primary posting keyword in the first eight words, then scope and outcome. MLOps or model deployment should appear by name, not as "ML infrastructure work."
Edge case: you were a data scientist who owned deployment because the platform team was understaffed. Say so in the bullet: "Owned end-to-end MLOps for churn models on SageMaker after platform backlog delayed Q3 releases." Edge case: consulting under NDA. Use client industry and model type without naming the brand: "Deployed fraud scoring models on Kubernetes for a payments client with 8M daily transactions."
Step 4: Spread infrastructure and monitoring terms across bullets two to four
One keyword cluster per bullet. Bullet two might carry CI/CD and Docker. Bullet three carries MLflow experiment tracking. Bullet four carries drift monitoring with Prometheus. Do not repeat the same deploy sentence with different adjectives.
Before: Four bullets all start with "Worked on MLOps pipelines using cloud tools."
After: Bullet two: "Automated model promotion with GitHub Actions and Terraform on EKS, reducing release cycles from two weeks to three days." Bullet three: "Added Grafana dashboards for latency and drift on twelve production endpoints."
Step 5: Trim Skills to terms you already proved, then parse-check
Skills should read like a short index: MLOps | Kubernetes | MLflow | SageMaker | Terraform | Python. Drop anything you cannot tie to a bullet or project line. Export PDF or DOCX, upload to a checker, and confirm Experience retained framework tokens in the right order.
For a faster tailoring loop on multiple similar reqs, see the ten-minute resume tailoring method for US job posts . Keyword placement is step three in that workflow, not a separate weekend project.
Copy-paste block: MLOps experience bullet bank
TAILORING WORKFLOW (per posting):
1. Highlight 6–8 terms from the ad (exact spelling)
2. Map each term → production role or project
3. Rewrite bullet 1: keyword in first 8 words + scope + outcome
4. Skills row = short mirror only

BULLET SKELETONS (swap bracketed terms):
• Built [CI/CD] pipelines for [TensorFlow/PyTorch] models on [Kubernetes/SageMaker], [metric]
• Deployed [model type] with [Docker/Kubeflow], serving [N] requests/day with [latency detail]
• Implemented [MLflow] tracking for [N] experiments, standardizing promotion gates for prod
• Monitored [drift/latency] with [Prometheus/Grafana], [alert or rollback outcome]
• Automated infra with [Terraform] on [AWS/Azure/GCP], [scope line]

SKILLS LINE (after bullets exist):
MLOps | Kubernetes | MLflow | SageMaker | Terraform | Python | CI/CD
Where MLOps keyword lists go wrong
These patterns show up on MLOps reqs where the candidate clearly ran pipelines but the file never proves it in the lines parsers rank first.
Skills-only orchestration with Data Scientist titles. Title says Data Scientist while every Kubernetes token sits in Skills. Hiring managers assume notebook work, not platform ownership. Move MLOps terms into employer bullets or retitle the project block honestly.
Research metrics without production scope. Accuracy and F1 scores belong when the req is modeling-heavy. Platform reqs want deploy frequency, rollback time, and monitoring coverage. Match the posting's emphasis.
Acronym soup without outcomes. "Kubernetes, MLflow, Airflow, Spark, Kafka, Feast, Ray" in one bullet and no user or metric. Split terms and attach each to something shipped.
Two-column or icon Skills grids. Workday and Taleo parsers read left column before right. Platform icons do not export as text. Use a single column and plain bullets.
Same file for ML Engineer and MLOps Engineer reqs. An ML Engineer posting wants modeling depth. An MLOps posting wants pipeline reliability and monitoring. One generic keyword dump serves neither.
Before: Summary: "Passionate ML professional skilled in the MLOps ecosystem." Experience bullets omit platform names.
After: Summary shortened to one line. Bullet one: "Owned MLOps for recommendation models on SageMaker, deploying twelve versions per quarter with automated drift checks in Grafana."
Parse-check before you upload
Tools confirm whether Experience or Skills carried your MLOps tokens after export. Paste the posting and your file into HireFlow's free ATS resume checker and read which section surfaced Kubernetes, MLflow, and CI/CD. If keywords only appear under Skills, rewrite bullet one before you apply.
When you're rebuilding from a research-heavy resume, build your resume in a single-column layout so deployment lines stay in Experience order. Re-export after every bullet pass. A parse preview beats guessing whether Taleo read your Skills column.
Do this now: Highlight eight terms from one target posting, rewrite bullet one with MLOps or deployment in the first eight words, trim Skills to match, run one parse check, then apply with that filename logged in your tracker.
What to do now
An MLOps resume keywords US ATS list is a map from the posting to the bullet where you shipped or monitored models. Skills repeats what Experience already proved. Parsers and recruiters read the dated lines first.
- Highlight six to eight terms from one target posting with exact spelling.
- Rewrite bullet one so deployment or MLOps lands in the first eight words with scope.
- Spread CI/CD, tracking, and monitoring terms across bullets two to four.
- Trim Skills to a short mirror, not a keyword warehouse.
- Run a parse check, then apply with the file that passed preview.
Open the req you're tailoring. Run a free ATS check , fix bullet one, and upload only when Experience carries the platform names the ad repeats.
Read more
Frequently asked questions
Lead with Experience bullets under the role where you deployed or monitored models. Parsers and recruiters weight dated production lines higher than undated keyword lists. Skills can repeat terms you already proved in bullets, but it should not be the only place Kubernetes, MLflow, or CI/CD appear. When Skills lists twelve platforms and every bullet says improved ML systems, the file reads like padding.
Aim for one infrastructure or framework term plus one outcome per bullet. Example: Kubernetes plus model rollback time, or MLflow plus experiment tracking for twelve data scientists. Stacking six acronyms in one line buries scope. If the posting repeats SageMaker and Terraform, split them across two bullets tied to different releases instead of one unreadable sentence.
Parsers match exact tokens from the posting. If the ad says MLOps Engineer, your title or summary should include MLOps, not only DevOps. Many reqs list both CI/CD and model monitoring. Mirror their spelling: MLflow versus ML Flow, Kubeflow versus Kubernetes alone. Do not assume the ATS connects model deployment to generic software engineer language if those terms never appear in Experience.
Match the posting order: model deployment, CI/CD, Docker, Kubernetes, a cloud ML service they name, and monitoring tooling. Add feature stores and data pipelines when the description asks. Senior postings add governance, drift detection, and cost optimization. Junior postings want one clear ship story from notebook to production. Pull six to eight terms from the ad, not from a generic master list.
Only if you actually ran pipelines or serving in that job and can describe them in a bullet. Side projects belong under Projects with stack and outcome, not under a full-time employer title. Recruiters verify orchestration claims against bullet detail in phone screens. A Skills line without a matching Experience or Project line is a common rejection trigger for MLOps reqs.