11 min read
Your PDF lists three strong ML builds. Workday shows TensorFlow under Education and nothing under Experience. That's the gap most candidates miss. You didn't fail on model quality. The export put a Kaggle URL where a company name should sit, and the parser attached framework names to the wrong block. US tech recruiters in Workday and Greenhouse ctrl-f production scope, deployment verbs, and stack names inside dated job rows before they'll open your repo.
Check your resume for free with the posting pasted in after you run the Notepad paste test on your master file. If github.com imported as your employer or PyTorch landed in a Skills sidebar that flattened after Education, structure broke before keyword tuning mattered. You won't fix that by adding another competition badge.
Job searching with a portfolio you're proud of is already slow. This page is a diagnostic, not a list of Kaggle ideas. You'll see the symptom recruiters notice, three causes that scramble ML project sections on import, how to tell which one hit your file, and the fix for each with before and after bullets you can paste tonight. No pep talk about passion projects. Just plain rows parsers can read.
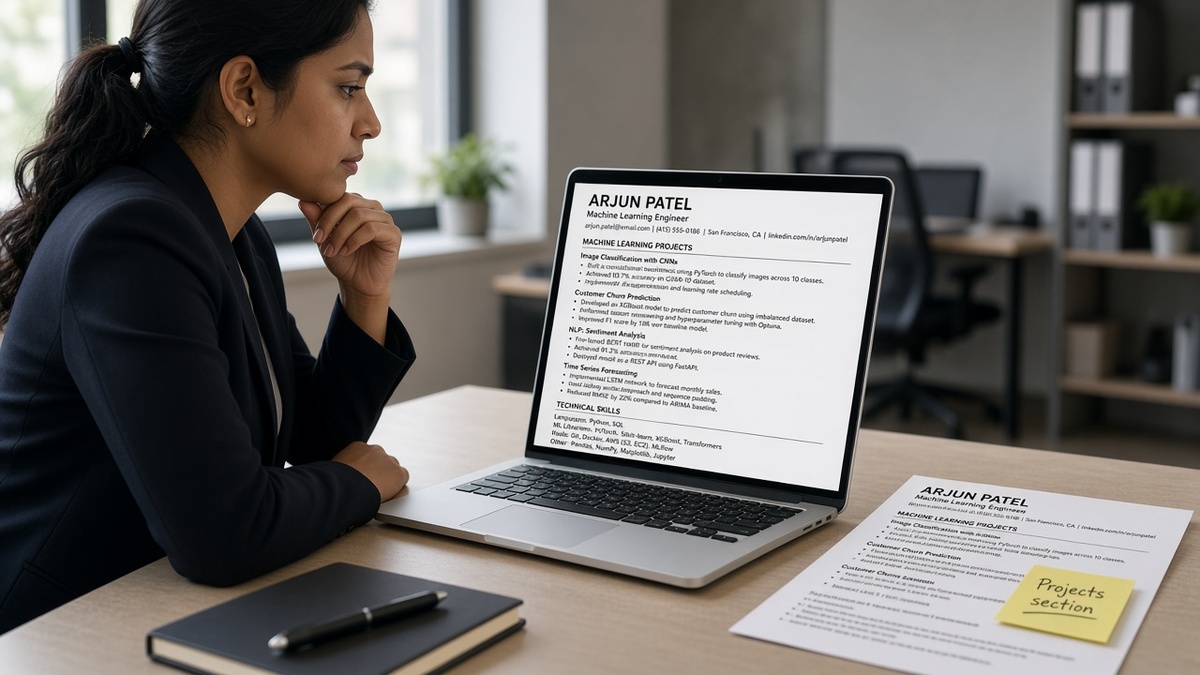
Open your master file now. Select the Projects block and paste into Notepad. If competition titles merged with TensorFlow into one string, keep reading. You're not losing on missing sklearn. You're losing on where the parser thinks your work lived.
And if you're tempted to stuff every framework into a Skills cloud, pause. I've screened Workday stacks where a solid ML intern file showed blank Experience because the template put tools left and jobs right. Fix the container before you rewrite bullet verbs for the fourth time.
Quick Wins
- Never put a Kaggle or GitHub URL where the employer name belongs.
- Put TensorFlow or PyTorch in bullet one under the job or project where you used it.
- Keep paid ML work in Experience; capstone and Kaggle rows go in Projects below jobs.
- Paste export into Notepad and confirm each project title starts on its own line.
The symptom: your ML projects look strong, the recruiter profile does not
The pattern repeats on ML engineer, data scientist, and applied scientist reqs. You upload a designed PDF with a Projects band, metric callouts, and framework icons. Greenhouse or Workday builds a candidate profile from extracted text. The coordinator opens the profile first. Experience looks thin. Education picked up TensorFlow. The churn model you spent months on sits as a URL string with no dates.
Recruiters are not ignoring your projects. The import order hid them. Parsers read a text stream top to bottom. When a project block uses tables, colored headers, or a repo link as the first line, employer detection misfires. Framework names in a left column often import after Education. Production bullets that lived beside a logo strip flatten into one paragraph nobody ctrl-f's.
A composite ML engineer whose PDF shows Kaggle top 5% and a deployed FastAPI service loses to the same facts on boring lines: employer or project title, Month Year or project date, bullet one with stack and metric. Same qualifications. Different skim surface for a recruiter verifying you shipped models, not only trained them in a notebook.
Edge case: bootcamp grad with one internship and four class projects. Recruiters expect Projects below a short Experience block. Do not invent a fake employer called Machine Learning Projects. Use a plain Projects heading and title each build. Cap the section at four rows so the file stays one page.
Edge case: PhD moving to industry ML. Publications stay in Publications or Education. Applied pipeline work from the lab belongs in Experience with university employer name and RA title, or in Projects with clear applied labels. Parsers do not merge journal names into Experience when you nest them in tables.
Read how ATS maps resume sections when your ML tools keep attaching to the wrong heading for the same layout reasons as finance and marketing files.
ML projects on resume: three parsing failures recruiters see first
Match your last silent screen to one cause before you add another competition. All three show up on otherwise strong files.
Cause 1: Kaggle or GitHub links replace employer lines
Templates marketed to data scientists put repo URLs on the left where Workday expects Company Name. The parser reads github.com/user/churn-model as the employer field. Dates on the right orphan. Bullets import as free text with no job anchor. Recruiters ctrl-f company names and see a URL instead of your internship host.
Fix: Project title on line one. Link at the end of the block or on the contact line only. Paid work always uses real employer name and Month Year dates in Experience.
Before: github.com/janedoe/fraud-detection | 2024
Built XGBoost classifier; 94% precision on 2.1M rows.
After: Projects section plain text:
Fraud Detection Pipeline (personal project) | 2024
Trained XGBoost classifier on 2.1M transaction rows; held 94% precision on holdout set in Python.
Before: Kaggle.com/competitions/titanic listed as employer with no job title.
After: Kaggle Competition: Titanic Survival | rank 412 of 12,000 | 2023
Engineered features in pandas; tuned Random Forest to 0.82 public LB score.
Cause 2: Framework names only in Skills or Education sidebars
Two-column resume kits park TensorFlow, PyTorch, and Kubernetes in a left Skills column. On import, those terms often land under Education or between sections. Recruiters searching TensorFlow inside Experience get zero hits while your summary claims MLOps ownership. The model work was there. The parser filed it wrong.
Fix: Name the stack in bullet one under the employer or project where you used it. Skills holds six backup terms max. Single column start to finish.
Before: Skills column lists TensorFlow, PyTorch, MLflow, Docker, AWS, SQL with no dated bullets mentioning them.
After: ML Engineer Intern | Northwind Analytics | June 2024 to August 2024
Deployed churn model in TensorFlow on AWS SageMaker; cut inference latency 18% serving 40K daily requests.
Before: Capstone title in a table cell; PyTorch mentioned only in a footer Skills strip.
After: NLP Sentiment Classifier (MS capstone) | Jan 2024 to May 2024
Fine-tuned BERT in PyTorch on 50K product reviews; reached 91% F1 on validation set.
Cause 3: Production scope buried below notebook metrics
Candidates lead with accuracy scores from offline notebooks. Hiring managers on production ML reqs search deploy, monitor, retrain, and SLA language. When every bullet ends at validation AUC, recruiters assume coursework depth only. That is a wording failure stacked on top of layout, but it shows up most when project rows never imported as separate lines.
Fix: Bullet one names environment: batch vs real-time, data volume, and one business outcome. Bullet two holds model detail. Mirror posting verbs: deployment, monitoring, feature store, A/B test.
Before: Achieved 0.89 AUC on imbalanced churn dataset using gradient boosting.
After: Shipped weekly batch churn scores to Salesforce for 3 account tiers; 0.89 AUC held in production on 1.2M active users.
Before: Built CNN for image classification with 95% accuracy.
After: Containerized CNN inference with Docker on GKE; 95% top-1 accuracy on 30K daily warehouse images with p95 latency under 200ms.
How to tell which cause stopped your file
Paste your export into Notepad. If the first line under a role reads http, cause 1 is yours. If TensorFlow appears only after your degree line, cause 2 fits. If project bullets imported but every line stops at offline metrics while the posting screams MLOps, tune cause 3 after you fix layout.
Most ML screens stack a thin Experience block with a crowded Projects band. Fix cause 1 and cause 2 before you tailor keywords. A composite data scientist with four Kaggle medals and zero dated employer rows will not recover with better hyperparameter adjectives on the same template.
Edge case: contractor ML work through an agency. Write Agency Name (Client: Retail Brand) as plain text on the employer line when both matter. Put deployed model scope in bullet one. Recruiters in-house ctrl-f the brand they sell.
Edge case: open-source maintainer applying to platform ML roles. One Projects row for the library with stars and weekly download counts as illustrative scope. Paid employment still needs employer lines. Do not list pypi.org as company name.
Read how to list coursework on a resume when it helps when capstone projects overlap Education and you need a clean split parsers respect.
Copy-paste ML project export rule
Copy-paste before every corporate ML apply:
1. Paid ML work in Experience with employer, title, Month Year dates
2. Kaggle and personal builds in Projects with title line, not repo URL as employer
3. TensorFlow/PyTorch in bullet one under the row where you used them
4. Single column; no tables, icon strips, or framework sidebars
5. Bullet one: deployment or data volume plus one metric; bullet two: model detail
6. Save DOCX when allowed; paste into Notepad and confirm each row stands alone
Where ML project proof still lands in the wrong block
Before: Eight class assignments listed to show breadth. After: Three projects that mirror the posting family with two bullets each.
Before: Jupyter notebook screenshots embedded in the PDF. After: Plain text bullets; one portfolio link on the contact line if you need visual proof.
Before: Responsible for machine learning tasks under a generic internship title. After: Built demand forecast model in Python serving 200 SKUs; cut stockouts 12% in Q3.
Before: Semicolon chains listing pandas, numpy, sklearn, matplotlib, seaborn, plotly on one line. After: Three bullets with one stack mention each tied to an outcome recruiters can repeat in a hiring manager forward.
Before: Assuming the hiring manager always opens the PDF. After: Build for parsed text first. Many ML leads forward Greenhouse profiles in Slack without attachments.
Edge case: career switcher from software engineering to ML. Your production deploy bullets from SWE roles belong in Experience. New ML builds go in Projects until you have paid ML title history. Bridge bullets that name ML stack on real shipping work beat a Projects section full of tutorials.
Edge case: international candidate with company names recruiters do not recognize. Keep honest employer strings. Add one plain clause in bullet one with user scale or industry: fraud model for EU neobank, 800K daily events. Parsers keep the employer line; humans get context.
Workday is not punishing ML portfolios. It is reading export order from templates built for Dribbble, not import. Plain single-column files look dull and map correctly. That trade beats a fifth rewrite of accuracy adjectives while TensorFlow still sits under Education.
Candidates often add another Kaggle medal while the employer field still shows a URL. If Notepad prints one paragraph under Projects, new metrics will not help. Swap the container first. Then tune the words inside each line.
Parse check before your next ML apply
After you rebuild project rows and employer lines, run a free ATS check with the job description pasted in. Confirm must-have stack terms appear inside parsed Experience or Projects lines, not only in a Skills footer that imported cleanly while job blocks flattened.
When the req lists eight ML must-haves and your file feels thin on two of them, score your job match before you spend an hour rewriting notebooks for a role where layout still breaks import. Fix structure first, then close real gaps with dated proof in bullet one.
Rebuild ML project rows before the next apply
Strong ML projects on resume come down to plain employer and project lines that survive import, not another framework icon strip. Kaggle links in the company field, TensorFlow parked in sidebars, and notebook metrics without deployment scope drop proof recruiters ctrl-f before they open your repo. Single-column Word exports with bullet one carrying stack and outcome fix most corporate ML uploads without changing your track record.
Open your master file tonight. Move paid work into Experience with dates. Rebuild Projects with titles, not URLs. Paste into Notepad. Upload when each row stands alone. This will not fix applying to senior MLOps reqs with student-only notebooks. It stops qualified ML candidates from dying as a paragraph nobody skimmed.
When the posting asks for a cover letter, generate a cover letter that repeats bullet one scope in prose. Letter and resume should match; neither rescues a Kaggle URL sitting where your internship employer should be. Keep a Workday-safe master labeled ML_Upload.docx next to any designed portfolio PDF you use for networking. Boring filename, accurate import.
Read more
Frequently asked questions
Paid or internship ML work belongs in Experience with employer name, Month Year dates, and bullet one naming stack plus outcome. Personal, capstone, and Kaggle work belongs in a plain Projects section below jobs with project title on its own line, not a URL where the company name should sit. Parsers weight dated Experience rows higher than undated project blocks, so production scope must live under real employers when you have them.
Yes when you format them as project rows, not employer lines. Write Kaggle Competition: Customer Churn as the title on one line, then bullets with rank, metric, and tools. Never put kaggle.com where Workday expects a company name or dates will orphan and TensorFlow from the bullet may attach to Education. One GitHub link on the contact line or at the end of the project block is enough.
Sidebars, two-column templates, and skill clouds often import after Education. Framework names parked there attach to the wrong section in the recruiter view. Move TensorFlow, PyTorch, and scikit-learn into bullet one under the job or project where you used them, then keep six terms max in Skills as backup. Paste your export into Notepad and confirm each tool sits on the same line as the role title.
Three to four strong projects beat eight thin ones. Lead with projects that mirror the posting: NLP for NLP reqs, forecasting for analytics roles, deployment language when the req mentions MLOps. Each project gets two bullets max with one metric and one stack name in bullet one. Cut class assignments that repeat the same sklearn pipeline story unless you are a new grad with limited paid work.
One link on the contact line or after the project block is fine. Do not replace employer names with github.com URLs or parsers read the repo as your company. Recruiters ctrl-f production metrics inside Experience before they click repos. If the parsed profile shows blank job blocks, fix layout before you add another notebook link.