7 min read
It's 8:15 on a Monday. A recruiter opens Workday for a senior analyst role that posted Friday night. Two hundred applications already sit in the requisition. She doesn't start at candidate one and read PDFs in order. She opens the filtered view, types a title keyword, and sorts by application date.
Your resume might be brilliant on page two. It won't matter tonight if the parser put your current title in a blank field and you never appear when she searches "financial analyst." That's the gap most candidates don't see until they've applied for months without a single screen.
You're not trying to beat the ATS. You're trying to survive the recruiter's first search inside it.
Run an extraction test on the file you'll upload. Check your resume for free and confirm title, employer, and skills show in order. That's the profile she'll search before she ever clicks your attachment.
Need a cover letter for the same posting? Generate a cover letter after the resume fields parse cleanly so your name and contact match across documents.
Quick wins
- Plain single-column file so title and employer land in the right ATS fields.
- Mirror posting keywords in bullets, not only in a skills sidebar.
- Read the upload preview field by field before you hit submit.
Stage one: your application enters the requisition
Click submit and the ATS creates an application record tied to that job ID. Your name, email, and answers to knockout questions store immediately. The resume file queues for parsing, usually within seconds, sometimes a few minutes on heavy posting days.
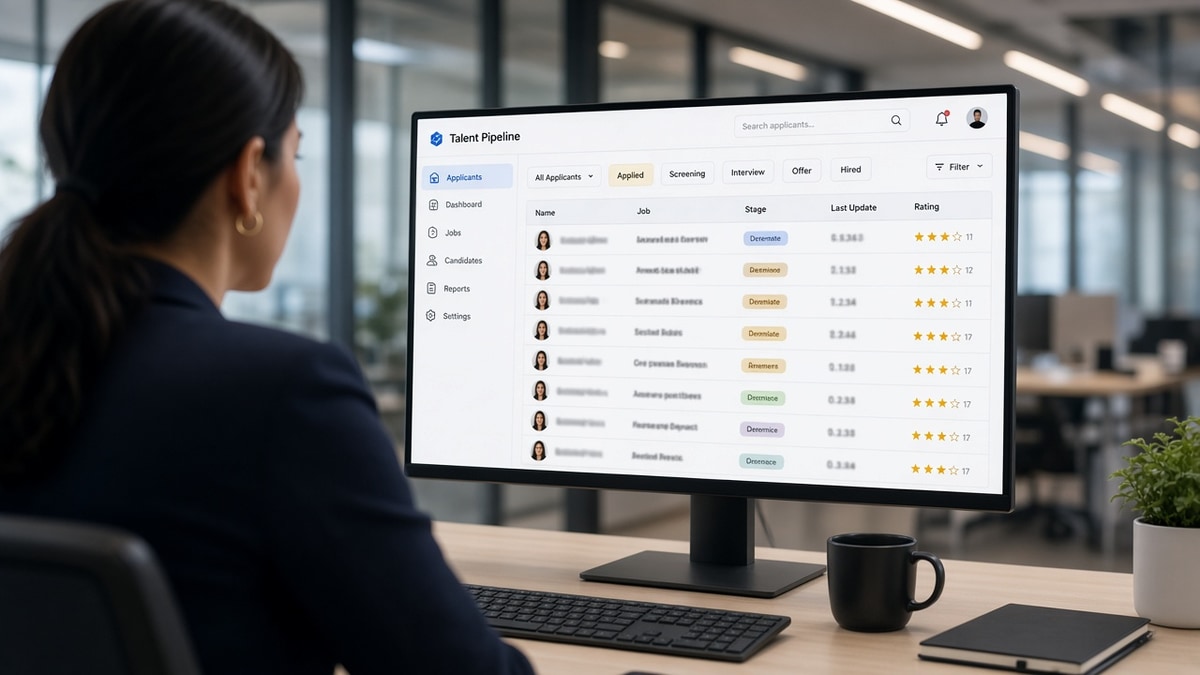
Recruiters rarely watch that import line by line. They work from the candidate grid once enough profiles populate. What they see first is structured data: current title, current company, location, years flagged by the system, referral source, and application timestamp.
Before: Candidate uploads a two-column PDF. Parsed profile shows "Graphic Designer" as current title because the sidebar label imported before the real job block.
After: Single-column DOCX with employer and title on separate lines. Parsed profile shows "Financial Analyst" at "Northwind Bank," matching what the recruiter will search.
Referrals and internal transfers may get a flag in the grid, but the parser still has to read your file. A referred candidate with a garbled upload looks the same as a cold applicant with blank employer fields until someone fixes the record manually.
Stages two through four: parse, filter, then human open
Think of the pipeline as four beats. Your goal is to survive each one with clean fields and searchable terms from the posting.
- Parser import: The ATS pulls text from your file into employer, title, date, education, and skills buckets. Broken layout means wrong buckets or empty strings.
- Automatic filters: Some reqs hide candidates who fail location, work authorization, or years-of-experience rules set by the hiring manager. You can't see those rules from outside; you only notice you never hear back.
- Recruiter search and sort: They combine keyword search ("SQL," "SOX," "SaaS") with filters on title and date. Profiles with missing title fields don't match even when the PDF mentions the term ten times.
- Attachment open: On the short list, they skim bullets, check tenure, and maybe forward five names to the hiring manager. This is the first moment a human reads your writing, not just your metadata.
Copy-paste title line recruiters search on:
Northwind Bank
Senior Financial Analyst
March 2020 to Present
• Built monthly variance decks for three business units in Excel and Looker
• Supported SOX testing on revenue recognition controls across two close cycles
I've passed on opening attachments when the grid showed a blank current employer but the requisition required Fortune 500 banking experience. The PDF might have listed Chase on page one. The parser never put it in the field I filtered on.
Before: Skills block in a left column reads before experience in plain-text export. Search hits "Python" but attaches it to the wrong job dates.
After: Python appears in a bullet under the data analyst role where you used it for twelve months. Title, employer, and skill stay tied together in the profile.
AI-assisted screeners sit in the same pipeline on some teams. AI resume screening before a human sees it covers what changes when ranking runs before a recruiter logs in.
Hiring managers sometimes get a smaller batch after recruiter screen. They still see the parsed headline first in many tools. A strong bullet on page two never loads if the manager never receives your name in the forwarded list.
Where candidates drop out before a read
- Upload preview ignored: blank phone or scrambled dates mean bad grid data forever on that application.
- Title mismatch: creative labels like "Revenue Wizard" don't match filters set to "Account Executive."
- Skills only in a graphic sidebar: search never sees them in structured fields.
- Applying without posting keywords in bullets: the profile exists but doesn't rank in keyword sort.
- Wrong file layer: image PDFs produce empty profiles recruiters skip in one glance.
Recruiters aren't ignoring you out of malice. They're working a queue built on fields your file fed the system. Fix the feed and you enter the same search results as candidates with weaker experience but cleaner parses.
Teams running two hundred open reqs don't have time to open every attachment. The grid is the first interview. Treat parsed fields like a headline you'd write yourself if you could control what recruiters see before the PDF loads.
Why manual resume review is almost gone explains how that queue replaced inbox attachments for most corporate reqs.
See your file like recruiters do
Extract text from your resume the way a parser would. Read only that dump for sixty seconds. If you can't tell current title and employer from the plain text, the recruiter grid won't either.
Run the ATS check on the file, fix any field that imports wrong, then re-upload to the live posting. Repeat until the preview matches your intent.
Generate a cover letter when the posting asks for one, using the same job title string you put in the Experience block so search terms stay aligned.
Win the grid before you win the read
How recruiters use ATS before reading resumes comes down to order: application, parse, filter and search, then attachment. Your PDF is step four. Steps two and three run on structured fields. Give the parser a plain file, mirror the posting in bullets, and verify the upload preview so you show up when someone types your title into the search bar.
Read more
Frequently asked questions
No. Recruiters work from a filtered list inside the ATS. They search and sort on parsed fields like job title, employer, skills, and location. Applications that don't parse into those fields or don't match active filters often never get opened as attachments.
The ATS stores your application record, runs the resume file through a parser, and maps text into structured fields. Recruiters see that profile in their requisition queue. A clean parse fills title and employer fields; a broken parse leaves blanks or scrambled dates.
They combine filters (location, years of experience, current title keywords) with keyword searches on skills and employer names. Some teams also sort by application date or referral flag. Your resume text only matters once you appear in that result set.
After you land in a short list from search or filter. They skim the parsed profile first, then open the attachment to verify bullets and formatting. If the profile already looks off, many recruiters skip the file and move to the next candidate.