12 min read
You've shipped PySpark jobs on Databricks, tuned shuffle partitions, and migrated batch ETL to Delta Lake, but your resume still says "worked with big data tools" and US recruiters searching "Spark" never pull your file. You're not failing screens on skill. You haven't wired keywords where parsers store them, and that's fixable tonight. Data engineering hiring's keyword-driven like every other lane, and vague bullets die in both ATS search and the technical screen.
Spark resume keywords and bullets for US roles need to name stack components, orchestration tools, and measurable pipeline outcomes inside dated Experience rows. Greenhouse and Workday store those tokens for recruiter boolean searches. A skills cloud that lists PySpark without throughput metrics won't carry you through.
Before you apply to the next data engineer req, check your resume for free with the full posting pasted in. I've screened data stacks where strong engineers got filtered because Databricks and EMR sat in a sidebar table parsers dropped while generic "ETL" bullets imported fine.
This guide covers the terms US hiring managers query, before-and-after bullets for pipeline owners, and edge cases like NDA work, title mismatch when HR says Software Engineer but you owned the data platform, and contract gaps. You can't bluff Spark in a live coding screen, but you can make sure parsers store the tools you actually run.
Quick Wins
- Highlight five repeated terms in your target data engineering posting.
- Rewrite bullet one under current role to include PySpark or Scala plus one data pipeline metric.
- Move Databricks or AWS EMR from Skills into a dated Experience bullet with scale.
What are Spark resume keywords in US data engineering hiring?
Spark resume keywords are the distributed compute, storage, and orchestration terms US employers use when hiring data engineers, analytics engineers, and platform engineers to build batch and streaming pipelines. They include Apache Spark, PySpark, Scala, Delta Lake, AWS EMR, Databricks, ETL, data pipeline, Kafka, Airflow, and cloud storage like S3 or ADLS.
Recruiters search these strings inside parsed resumes before they forward files to hiring managers. If your bullets only say "built data solutions," you will not match searches for "PySpark" or "Delta Lake."
**This is not** claiming Spark expertise because you ran a tutorial notebook once.
**This is** documenting pipelines you shipped with the vocabulary automated search and engineering managers both expect.
Data engineering hiring manager filter: I search PySpark and ETL first. If your bullets read like a ticket queue with no throughput numbers, I assume you never owned a production data pipeline.
Step-by-step: Spark keywords and bullets that rank
Step 1: Map posting language to your real pipelines
Pull five US data engineering reqs. Tag repeated nouns: PySpark, Scala, Delta Lake, AWS EMR, Databricks, Airflow, Kafka, dbt, Snowflake, Redshift, Glue.
Sort into pipelines you led versus pipelines you supported. Led work gets bullet one. Supported work gets bullet three with honest scope.
**Keyword skills block (trim to truth):** ``` Apache Spark, PySpark, Scala, Delta Lake, AWS EMR, Databricks, ETL, data pipeline, Apache Airflow, Kafka, Amazon S3, Parquet, partition tuning, CI/CD for data jobs ```
Step 2: Write bullets with stack plus metric
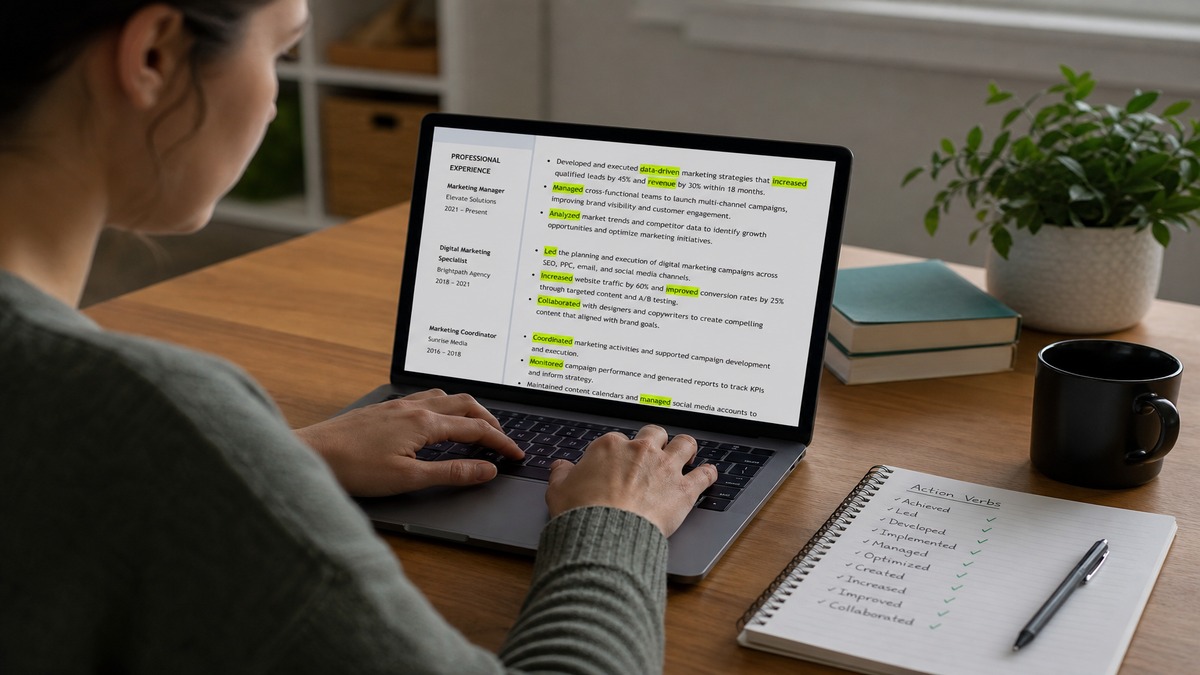
**Data engineer example:** Before: "Built ETL pipelines using Spark for analytics team." After: "Developed PySpark ETL data pipeline on Databricks ingesting 1.2TB daily from Kafka to Delta Lake; cut batch runtime from 4 hours to 55 minutes through partition pruning and broadcast joins."
**Senior data engineer example:** Before: "Managed big data platform on AWS." After: "Operated AWS EMR Spark cluster (12 nodes) processing 800M events/day; migrated 40 legacy Hive tables to Delta Lake with ACID merges, reducing downstream freshness SLA from T+1 to near real-time."
Stack name, tool, scale, measurable outcome.
Step 3: Show batch and streaming when true
US data reqs often want both batch ETL and streaming. Pair Spark Structured Streaming with batch work when you ran both.
**Copy-paste bullet patterns:** "Built Spark Structured Streaming job on EMR reading 50k events/sec from Kafka; landed bronze-silver-gold Delta tables with 15-minute latency." "Orchestrated 30 nightly PySpark jobs in Airflow on Databricks; 99.5% on-time SLA over 12 months." "Implemented slowly changing dimensions Type 2 in Delta Lake for 120M customer records with merge logic in Scala."
Pick patterns you ran. Add your numbers. Delete the rest.
Step 4: Name cloud and warehouse targets
Spark rarely exists alone. Pipelines land in Snowflake, Redshift, BigQuery, or S3 data lakes. One destination mention per bullet is enough.
**Example:** "Loaded curated PySpark outputs to Snowflake via S3 staging; reduced warehouse load windows 40% through incremental merges."
Use job match score to see which warehouse terms a specific posting weights highest.
Step 5: Handle data engineering edge cases
**Edge case: NDA pipelines** "Built PySpark ETL data pipeline for Fortune 100 retailer (NDA); 3TB daily clickstream to Delta Lake on Databricks with PII tokenization."
**Edge case: title mismatch** HR title "Software Engineer II" but you owned data platform. Summary: "Software engineer operating as data platform lead; 6 years PySpark and Airflow in production."
**Edge case: bootcamp or career switch** Lead with production contract or internship pipeline work. One strong metric beats ten course project names.
Edge case: gap between contracts
Stack contract data work under Consulting with month-year dates. Add one bullet on skills maintained: "Completed Databricks certified data engineer exam during gap; built open-source Airflow DAG sample processing public weather API." Gaps without learning signals worry hiring managers more than gaps with certs.
Step 6: Performance and cost keywords
Engineering managers search for candidates who tune clusters, not only write jobs.
**Before:** "Optimized Spark jobs for better performance." **After:** "Reduced EMR cluster spend 35% ($18k/month) by rightsizing executor memory and enabling adaptive query execution on 25 production PySpark jobs."
Cost and latency metrics separate senior files from junior ones.
Step 7: Data quality and testing bullets
Modern stacks expect Great Expectations, dbt tests, or custom validation. When true, pair ETL with quality outcomes.
**Before:** "Ensured data quality in pipelines." **After:** "Implemented Great Expectations suites on 15 critical PySpark outputs; cut production data incidents from 6/quarter to 1/quarter."
Composite example: analytics engineer with Spark
**Before:** "Supported analytics data needs." **After:** "Built PySpark transformations feeding 200+ dbt models in Snowflake; standardized event schema across 8 product teams and improved dashboard load time 50%."
Spark plus downstream tooling plus metric reads credible to platform leads.
Copy-paste summary for data engineer lane
"Data engineer with 7 years building batch and streaming pipelines; PySpark and Scala on Databricks and AWS EMR; owns ETL for 2TB+ daily with Delta Lake and Airflow orchestration."
Swap scale and cloud per application.
Step 8: Scala versus PySpark positioning
Postings that say Scala often want JVM performance work or legacy cluster code. PySpark postings skew toward notebook teams and ML feature stores.
If you wrote both, lead with the posting language: "Maintained 40 production Scala Spark jobs on EMR; refactored 12 critical paths to PySpark on Databricks during cloud migration."
Do not list Scala if your only exposure was reading someone else's jar.
Step 9: Glue, Lambda, and serverless Spark mentions
AWS Glue and Lambda appear in hybrid ETL reqs. Mention only if you operated them in production.
**Example:** "Migrated 8 nightly Glue Spark jobs to Databricks; unified orchestration in Airflow and cut failed runs 60%."
Step 10: Lakehouse and medallion architecture keywords
Delta Lake, Iceberg, and Hudi show up in lakehouse postings. Bronze-silver-gold layering is searchable language when you built it.
**Example:** "Designed medallion architecture on Delta Lake with PySpark; bronze ingestion from S3, silver deduplication, gold aggregates serving 30 Tableau dashboards."
Platform engineer collaboration bullets
Data engineers often partner with DevOps on CI/CD for jobs. When true, show joint outcomes.
**Example:** "Partnered with platform team to containerize PySpark jobs in Kubernetes; cut deploy time from 2 days to 2 hours with GitHub Actions and Databricks repos."
Step 11: Real-time and CDC keywords
Change-data-capture and Debezium appear in streaming reqs alongside Spark.
**Example:** "Built CDC pipeline from PostgreSQL via Debezium to Kafka; Spark Structured Streaming merged upserts into Delta Lake with 5-minute end-to-end latency."
Step 12: Security and governance in data pipelines
Enterprise reqs mention IAM, encryption, and column-level security. Pair ETL with governance when you owned it.
**Example:** "Enforced row-level security tags in Databricks Unity Catalog across 500 tables; automated PII masking in PySpark before landing to gold layer."
Copy-paste PySpark bullet bank
Pick two that are true:
• Migrated 25 TB on-prem Hadoop workloads to AWS EMR Spark; decommissioned 3 legacy clusters saving $220k annually. • Built feature store ingestion PySpark jobs feeding ML training sets with 4-hour freshness SLA. • Tuned skewed joins on 500M-row fact table; reduced single-stage shuffle spill from 800GB to under 50GB. • Implemented idempotent Delta Lake merges for daily sales ETL with automatic schema evolution.
Step 13: Observability and pipeline monitoring
Production data teams track job failures, data drift, and SLA breaches. When you owned alerting, say so with tools and outcomes.
**Before:** "Monitored data pipelines and fixed issues." **After:** "Built Datadog dashboards and PagerDuty alerts on 45 Airflow DAGs; cut mean time to detect failed PySpark jobs from 6 hours to 12 minutes."
Observability keywords help in platform-heavy reqs where uptime matters as much as throughput.
Step 14: Migration and legacy Hadoop keywords
Many US employers still run Cloudera or on-prem Hadoop and want migration stories. Honest framing wins screens.
**Example:** "Led Hadoop-to-Databricks migration for 200+ MapReduce jobs; rewrote critical paths in PySpark and retired 4 on-prem racks within 9 months."
Migration bullets show you can operate in messy enterprise environments, not only greenfield notebooks.
Quick reference: Spark keyword checklist
Before you apply, confirm your latest role mentions at least three of: Spark, PySpark, ETL, data pipeline, Delta Lake, EMR, Databricks, Airflow, or Kafka. Missing terms belong in bullet one, not footnotes.
Common mistakes
Listing tools from a bootcamp without production scale. Screens expose gaps fast. Keep pipeline ownership honest.
Generic big data bullets. No recruiter searches big data. They search PySpark, ETL, Delta Lake.
Two-column resume with logo headers. Enterprise data roles still parse through Workday. Use single column.
Spark in Skills with no Experience proof. Skills alone rarely survive recruiter search then technical screen.
Verify Spark keywords before you submit
Run the free ATS resume checker with a data engineering posting. Confirm Spark, PySpark, ETL, and data pipeline terms appear in Experience rows parsers index.
Use job match score to weight Databricks versus EMR gaps before you rewrite bullets.
Use the cover letter generator for roles that request letters. One paragraph on pipeline scope plus one throughput metric is enough.
Spark proof lives in dated bullets
US data engineering recruiters find candidates by searching Spark, PySpark, ETL, and data pipeline terms inside parsed Experience text.
- Mirror posting stack language honestly.
- Pair each Spark keyword with throughput, cost, or latency metrics.
- Handle NDA work with pattern descriptions, not buzzwords.
Stop hiding real pipeline work behind vague big data lines. Check your resume for free and confirm recruiters can search what you actually shipped.
Read more
Frequently asked questions
Common searches include Apache Spark, PySpark, Scala, Delta Lake, AWS EMR, Databricks, ETL, data pipeline, Airflow, Kafka, and S3. Match the posting's exact strings inside dated Experience bullets.
Both help, but Experience carries the screen. A skills cloud without pipeline metrics will not survive recruiter boolean search followed by a technical interview.
Lead with whichever language the posting names first. Mention the other once in the same role if you wrote production jobs in both. Do not claim Scala if you only edited notebooks.
Describe scale and patterns without naming the client: Built PySpark ETL data pipeline processing 2TB daily events on Databricks with Delta Lake ACID tables.
Yes. Enterprise data hiring runs through Greenhouse and Workday like every other function. Single-column PDFs with standard headings parse best.