12 min read
Your resume can look perfect on screen and still die in the upload because the parser reads columns, tables, and headers in an order you didn't intend. That's how layout choices affect resume parsing in practice: not keyword density first, but read order. Workday, Greenhouse, Lever, and Taleo build a text profile from your file before a recruiter opens the attachment.
Check your resume for free with the posting pasted in after you walk the steps below. If plain-text export shows Skills before your current employer, you've found the leak. Job searching's hard enough without retuning keywords on a file the parser's already scrambled.
Below: a six-step procedure to export, collapse, and retest layout, two edge cases recruiters still see, before/after pairs across roles, mistakes that look modern but break parsers, tool checks, and FAQs on PDF versus Word. You'll run step one in five minutes on the file you're about to submit. When a posting also wants a letter, draft structure in the cover letter generator only after the resume plain-text test passes.
Quick Wins
- Export plain text. If order feels wrong, fix layout before keywords.
- One column, standard headers, Month Year dates beside titles.
- Move contact lines out of headers and footers into the body.
- Drop tables, icon skill bars, and text boxes holding experience.
What parsers read before a recruiter sees your design
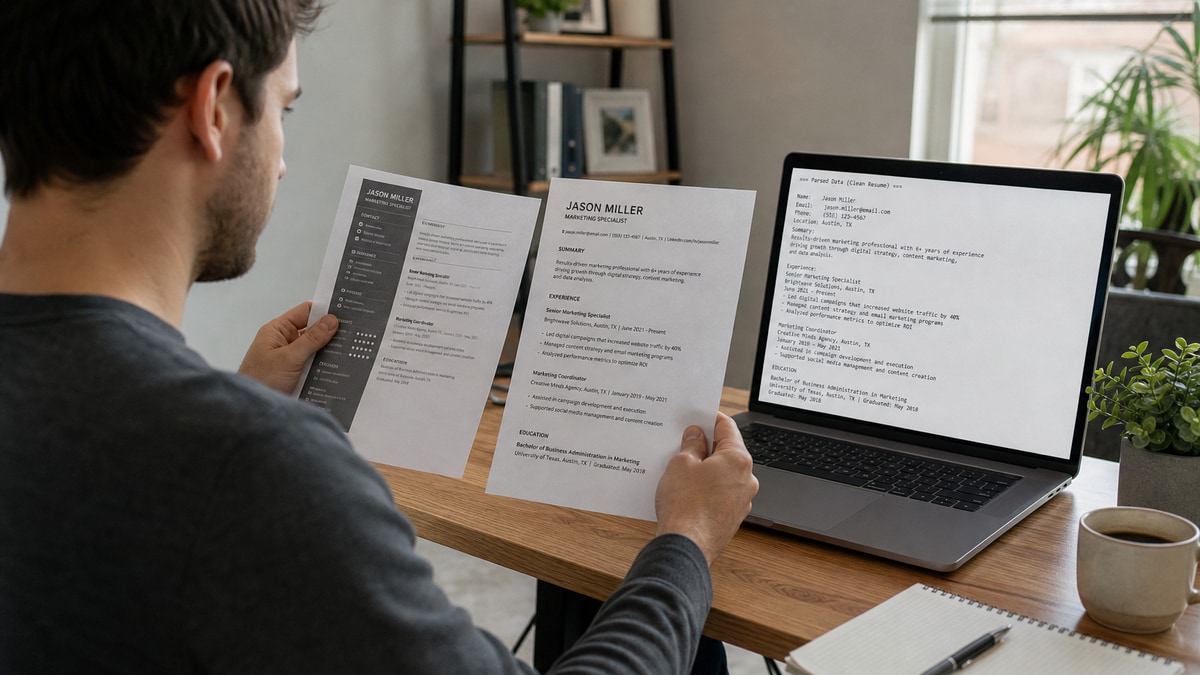
Applicant tracking systems do not admire your template. They strip text into a stream, tag sections when headers match known labels, and pair lines heuristically. Multi-column layouts interrupt that stream. A left rail of skills can parse as if it were your most recent job. A table cell holding a KPI may never surface in keyword search because the parser skipped the grid.
Layout is read order, not decoration. Recruiters screening in Workday often open the parsed profile first. If your current title paired with the wrong company, they may never download the PDF that looked flawless in Canva. The failure feels like silence or instant reject when the real issue was a sidebar.
A composite marketing coordinator used a two-column Canva export. Plain text showed Adobe Creative Suite and Google Analytics before her employer name. Greenhouse attached those tools to a blank role row. She spent a week rewriting summary keywords. One single-column rebuild fixed the pairing without changing a single bullet verb.
Edge case: some modern PDF generators preserve reading order well enough that a mild two-column contact line survives. Still run plain-text export. Mild exceptions do not justify portfolio templates with skill grids on page one.
Edge case: academic CVs with long publication lists. Length is fine in one column. Problems start when publications sit in a table beside employment history. Split sections vertically instead of side by side.
Font choice matters after layout. Stick to Calibri, Arial, or Times New Roman at 10.5 to 12 points. Decorative script headers sometimes parse as blank lines, which makes the next bullet look like a job title. Bullet characters should be standard dots or hyphens, not custom icons from a template pack.
Page breaks are safer than column breaks. A two-page single-column file usually parses in order page one then page two. A one-page two-column file often interleaves left and right rails. If you need two pages, keep section headers repeated only when necessary and never move Skills back to page one in a sidebar on page two.
Read why applicants feel ignored when silence follows upload. Filter silence from parser mismatch is common when layout breaks before keywords get scored.
Six steps when layout choices affect resume parsing
Work the steps in order. Do not jump to keyword tweaks until plain-text export reads like a sane career story top to bottom.
Step 1: Export plain text and read order aloud
Open the PDF in a viewer that shows text order, or save as .txt from Word. Read from line one. Name, contact, current job title, company, dates, bullets. If Skills or a summary box interrupts before employer lines, note the break. That break is what the parser likely hits.
On Mac Preview, select all and paste into a blank doc to see order. On Word, Save As plain text. On Adobe, export to text. Different tools expose the same problem: rails and tables jump ahead of Experience. Screenshot your plain-text output and keep it next to the posting while you fix layout. It is faster than uploading three broken versions to the same req.
Before: Plain text opens with Python, SQL, Tableau, then a blank line, then a job title from two roles ago.
After: Name, email, phone, Experience header, current title, company, March 2022 to Present, first bullet with Python in the sentence.
Step 2: Collapse to a single column
Move every sidebar block into the main body. Delete text boxes and floating shapes. Keep one vertical stack per role. If you love a visual divider, replace it with a blank line, not a column break.
Before: Two-column Canva template with contact and skills on the left, jobs on the right.
After: 11-point Calibri or Arial, one margin, jobs listed newest first in a single stream.
Step 3: Standardize section headers
Use Experience, Education, and Skills as plain text headings on their own lines. Creative labels like My Journey or Value I Bring confuse classifiers. Bold is fine. Icons beside headers are not.
Subsections inside Experience do not need their own H1-style blocks. One employer block equals title line, company line or combined line, dates, then bullets. Certifications can sit under Education or in a short Certifications header below Skills. Avoid nesting Certifications inside a table beside Education. iCIMS and Taleo map unknown headers to miscellaneous buckets where keywords go to die.
Step 4: Pull contact info into the document body
Many parsers skip header and footer regions. Put name, phone, email, city, and LinkedIn URL on lines one through five in the main body. Do not hide email inside a Word header field.
Before: Phone number only visible in a PDF footer on page two.
After: Phone and email directly under the name on line two and three, visible in plain-text export.
Step 5: Pair dates with titles inline
Right-aligned date columns detach in many parsers. Put Month Year on the same line as title and company, or immediately below on its own line under the title. Example: Senior Analyst, Contoso, January 2021 to March 2024.
Before: Dates in a table column far from job titles.
After: Operations Manager, Fabrikam, June 2019 to August 2022, followed by bullets on the next lines.
Step 6: Retest and submit the clean export
Export plain text again. Run the file through a free checker with the posting pasted in. Submit the version that preserves order. Keep a copy of the broken layout as a reminder, not as the file you upload.
Portal preview beats guessing when Greenhouse or Lever shows a parse screen. If the preview still swaps employers, return to step two even if your Word doc looks fine on screen. Some PDF exporters flatten columns badly while DOCX from the same source reads clean.
Role-specific layout traps
Designers and marketers often use portfolio layouts with project grids. Each project should become a bullet under the employer where you shipped it, not a three-column gallery on page one. Engineers sometimes hide a long stack in a sidebar while bullets stay generic. Move stack terms into the bullet where you built with them. Operations candidates paste KPI tables from slide decks. Turn each KPI into one bullet with Month Year context on the role line.
Before: UX designer resume with six project tiles in a table above Experience; plain text lists Figma before any job title.
After: Experience header, Product Designer at current shop, March 2023 to Present, first bullet names Figma prototype that cut checkout steps.
Before: Data analyst file with Python and SQL in a left rail; current title pairs with Looker in the parsed profile.
After: Analyst role line, dates inline, bullet opens with Built churn model in Python and SQL, surfaced in Looker weekly review.
Copy-paste layout audit block
Plain-text line 1: [name visible Y/N]
Contact before first job: [Y/N, should be N except name/email/phone]
Columns or tables: [Y/N, should be N]
Headers used: Experience / Education / Skills [Y/N]
Dates beside titles: [Y/N]
Header/footer-only content: [list any]
Parser risk: [low / fix before submit]
Fill the audit block before you tailor keywords. It takes three minutes and saves another week guessing why required terms never land under the right employer in Workday.
Read cover letter differences for US government jobs when your layout is clean but the posting also demands a separate narrative format.
Design habits that still break parsers in 2026
You trust the visual PDF. Pretty and parseable diverge often. Plain text is the referee.
You keep a Skills icon grid on page one. Icon fonts turn into squares. Skills without job context do not score the way you think.
You use tables for employment history. Cells hide row boundaries from the parser. Vertical stacks survive.
You put keywords only in a footer keyword block. Some systems never index footers. Mirror terms inside Experience bullets.
You submit a scanned photo of a printed resume. OCR garbles titles. Rebuild as text in Word, then export PDF.
You nest jobs inside one table row per company. Parsers often read across cells and merge two roles into one title line. Stack roles vertically with their own date strips instead.
You use Word text boxes for a summary callout. Callouts float outside the main stream. Fold summary lines into bullet one under your current role or drop the summary entirely when bullets already show scope.
I've opened thousands of parsed profiles in Workday and Greenhouse where the attachment was gorgeous and the profile row was nonsense. Layout fixes beat another round of keyword stuffing every time.
Verify layout before you tailor keywords
Run the posting and file through the free ATS checker. If required skills show up only under Education or a blank row, layout still leaks. Fix steps two through five before you rewrite bullet verbs.
Use Score your job match after plain text passes. Low match on a readable file means keyword gap. Low match on a scrambled file means layout first, keywords second.
Tools will not redesign your template for you. They show whether the parser sees what you see. Pair the score with the copy-paste audit block so you are not guessing.
When a posting lets you paste a LinkedIn URL instead of a file, layout still matters for the PDF you attach later in the thread. Recruiters often download the same file you tested. One clean export across portal, email, and referral paths saves rework.
If you're switching from a creative template to a plain file, keep a designed version for human networking events but upload the plain export to Workday, Greenhouse, and Lever. Two versions is normal. One pretty deck and one parser-safe PDF beats one file that fails both gates.
Run the plain-text test tonight
How layout choices affect resume parsing comes down to read order. Columns, tables, headers, and icon grids change that order even when the PDF looks hire-ready. Export plain text, collapse to one column, standardize headers, move contact into the body, pair dates with titles, retest.
Open the file you planned to submit tomorrow. Run the copy-paste audit block. If risk is not low, rebuild before you touch keywords. Then run a free check against the posting.
Save the plain-text export with today's date in the filename so you can compare the next time you tweak layout. When order holds across two exports, keyword tailoring finally compounds instead of leaking into the wrong employer row.
A qualified story in the wrong layout still reads as unqualified in the parser. Fix order first. Tailor second. Submit third.
Read more
Frequently asked questions
Not always on every system, but the failure mode is common enough to treat columns as guilty until plain-text export proves otherwise. Parsers read left to right across the page before moving down. A sidebar Skills rail can parse before your current job title, pairing keywords with the wrong employer. Single-column layout removes that gamble.
Simple one-row contact lines sometimes parse. Multi-row tables for experience, skills grids, or KPI callouts often trap text inside cells the parser skips or reads out of order. If your table holds anything beyond name, phone, and email on one line, rebuild that section as vertical bullets instead.
Submit what the portal accepts, then verify with a plain-text read. Text-based PDF exported from Word usually matches DOCX order. Canva PDFs, scanned files, and portfolio exports often drop bullets or shuffle sections even when the visual PDF looks fine. When preview scrambles on PDF, retry DOCX from the same single-column source.
Icon fonts and skill bars frequently become blank squares or random characters in the text stream. Some parsers ignore the whole block. Replace icons with plain text skill names inside Experience bullets where you used the tool. A comma list in a vertical Skills section is fine when it sits below Experience, not in a sidebar.
Light use of bold for section headers usually survives. Heavy color blocks, text boxes, and background shapes still confuse extraction on some stacks. The test is always the plain-text export: if order holds and nothing turns to gibberish, mild formatting is probably fine. If headers vanish, simplify further.