11 min read
You've applied to twelve roles this week and you're not sure whether the resume or the market is the problem. I've screened stacks of files where the candidate was qualified but the CV never surfaced because keywords and formatting failed before a human opened it.
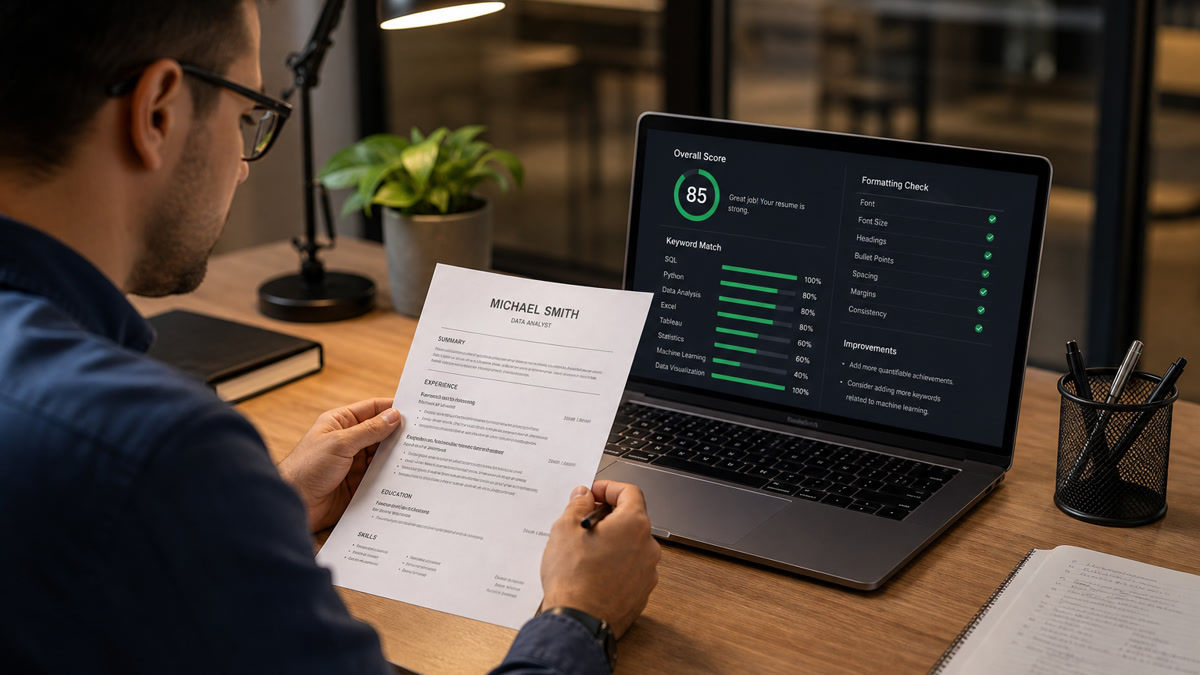
A resume check using data analytics to refine your CV isn't about dashboards for fun. It's about treating each application like a small experiment. Before you edit tonight's batch, check your resume for free against one posting you actually want. You'll see which gaps are fixable in thirty minutes and which roles need a different bullet, not another paragraph of fluff.
Most job seekers guess. They tweak a summary line, upload, and hope. Data-driven refinement means you log what changed, what the checker flagged, and whether the score moved on the same job description. That loop beats rewriting the whole document every Sunday.
This guide walks through what to measure, how to read checker output without obsessing over a single number, and copy-paste edit patterns for analysts, nurses, and ops roles. You don't need a statistics degree. You need a baseline file, one target posting, and a habit of fixing one layer at a time.
Quick Wins
- Run a baseline scan on your master resume with no posting pasted in. Fix every formatting flag before you tailor keywords.
- Paste your top target posting into the checker and list the three missing required skills in a notes column.
- Swap one bullet per missing skill, then re-scan the same posting before you upload. Log the before and after score in a simple sheet.
What does a resume check using data analytics actually measure?
A data-driven resume check compares your file against what parsers and rankers expect: readable structure, standard section labels, keyword overlap with the posting, and proof that required skills show up in experience lines, not just a skills dump at the bottom.
Analytics here means repeatable reads, not vanity metrics. You capture a score or match label, the specific gaps flagged, and which version of the file you tested. Next week you can see whether your ops resume still dies on the same missing term or whether your edits actually stuck.
This is not the same as keyword stuffing. Posting language should appear where you have real proof. If the checker says Python is thin, you add a bullet with a project and a metric, not twelve instances of the word in your summary.
Recruiter filter: I care whether your latest role reads like the job I posted. A high generic score with the wrong job title spelling still gets skipped.
Read how resume scores are calculated when you want the breakdown behind formatting, keywords, and match buckets before you start logging numbers.
Step-by-step: resume check using data analytics to refine your CV
Step 1: Establish a clean baseline file
Upload your master resume without a job description first. Formatting failures hide keyword work. Tables, text boxes, and creative section headers break parsers in Workday and Greenhouse before anyone scores your SQL line.
Before: Two-column layout with icons, skills cloud, and "Professional Journey" as the experience header.
After: Single column, standard "Work Experience" label, Arial or Calibri at 11pt, saved as text-based PDF or DOCX.
Edge case: Design-forward portfolios for creative roles still need a plain-text ATS version. Upload the plain file to corporate portals; send the portfolio link in a follow-up or application note field when allowed.
Step 2: Run a posting-specific match scan
Paste the full job description for one role you want this week. The checker compares required and preferred terms against your experience section. Missing items are your edit list, not a reason to panic-apply anyway.
Before: Generic summary: "Results-driven professional with strong communication skills."
After: "Supply chain analyst with three years of demand forecasting in Excel and SAP, focused on SKU-level accuracy for a 400-SKU catalog."
Log the date, company, role title, score or match tier, and the top three gaps. That row becomes your experiment record when you refine your CV for the next similar posting.
Step 3: Prioritize gaps by must-have vs nice-to-have
Not every flagged keyword deserves a new bullet tonight. Sort gaps into required skills in the first screen paragraph, preferred skills you can show with adjacent proof, and noise terms that appear once in a long posting.
Data analyst example: Posting requires SQL, Python, and stakeholder reporting. You have SQL and Python in bullets but reporting lives only in a skills list.
Fix: Move reporting into a bullet: "Built weekly KPI decks for four directors, cutting ad-hoc data requests from twelve per week to three."
Edge case: Posting asks for a certification you lack. Do not fake it. Either show equivalent coursework in a project bullet or deprioritize that apply unless the employer invites career changers.
Step 4: Edit one layer, then re-scan the same posting
Change formatting only in pass one. Pass two swaps bullets and adds metrics. Pass three adjusts summary and skills lines. Re-run the checker on the identical job text after each pass so you know which edit moved the needle.
Operations coordinator example:
Before: "Responsible for scheduling and vendor coordination."
After: "Coordinated 18 vendor renewals in Q2, consolidating contracts to save $42K annual spend while keeping SLA breaches at zero."
Sounds simple, right? Most resumes still bury the number in a vague duty line. Analytics only help when the after version is measurably different, not when you swapped two synonyms.
Step 5: Build a version tracker, not twenty random files
Name files with role family and date, not "resume_final_v9." Example: Miller_Resume_Analyst_2026-03.pdf for data roles and Miller_Resume_Ops_2026-03.pdf for operations targets.
Your tracker columns: role title, posting URL, check date, score, gaps fixed, file name uploaded. When a callback lands, note which version they saw. That tells you which analytics-driven edits actually correlate with human interest.
Copy-paste bullet upgrade blocks (edit every bracket)
Missing technical skill: "Built [tool] workflows for [team size], [metric outcome], using [posting keyword] daily across [time period]."
Thin leadership signal: "Led [number] [project type] with [stakeholder group], delivering [metric] while mentoring [number] junior [role type]."
Career changer bridge: "After [credential or bootcamp] in [year], shipped [project] that [metric], matching your need for [posting phrase]."
Read how to create a master resume and tailor from it when you are deciding how many base versions to maintain instead of one mega file.
Edge case: batch applying to similar titles
When ten postings share 80% of the same keywords, check one representative description, fix the master family file, then spot-check two outliers that mention unusual tools. You do not need twenty separate analytics runs if the skill stack is identical.
When titles differ materially, like analyst versus engineer, split files. Mixing keyword sets on one CV often produces a middling match on both and a strong match on neither.
Edge case: senior candidates with long histories
Analytics will flag keyword gaps on older roles you no longer want to lead with. Trim early bullets, keep titles honest, and front-load the last ten to twelve years that mirror the posting. Senior files fail when the first screen shows unrelated scope from 2008.
Before: Page one lists six jobs with equal depth.
After: Three recent roles with metric-heavy bullets; older roles collapsed to title, company, and one line unless directly relevant.
Second composite: registered nurse targeting ICU
Before: "Provided compassionate patient care on a busy unit."
After: "On a 28-bed ICU I managed ventilator and sedation protocols for up to four patients per shift, maintaining central-line bundles that kept CLABSI rates below unit benchmark through a 2025 staffing surge."
The checker moves when Epic, ICU, and measurable outcomes appear in experience lines. A skills list that says "critical care" without context rarely shifts match scores enough to matter.
Edge case: international CV vs US resume format
CVs with photo, birth date, and multi-page publication lists confuse US ATS parsers. Run the US-formatted version through the checker first. Keep the long CV for academic or EU portals that expect it, but do not upload that file to a US corporate req without a conversion pass.
Strip headers and footers that repeat your name on every page. They look polished to humans and break merge fields for parsers.
Common mistakes when using resume analytics
Chasing a perfect score on a generic file. A 95 on a master resume means little if the posting wants Kubernetes and your file still leads with help-desk tickets. Match the req you are submitting tonight.
Keyword stuffing after a low match. Repeating "stakeholder management" nine times tanks human readability and can trigger quality filters. One strong bullet beats nine weak mentions.
Ignoring formatting flags. Candidates often tweak summary lines while the checker still shows table parsing errors. Fix structure before vocabulary.
No version log. You cannot tell which edit earned a callback if every upload is resume_new.pdf. Analytics without a tracker is just anxiety.
Applying when must-haves stay red. If required certification or years of experience cannot be shown honestly, the data says skip or network in. Submitting anyway burns time and morale.
Mismatched claims versus bullets. If the summary says "expert in Python" but no bullet mentions Python, recruiters notice instantly. Align summary, skills, and experience before you trust a higher score.
Use HireFlow to run your resume check loop
Upload your file to HireFlow's free ATS resume checker with the posting pasted in. Read formatting flags first, then keyword gaps, then overall match. That order mirrors how parsers fail in real portals.
For role-fit before you rewrite, try job match score to see which requirements need a new bullet versus a one-word tweak. Pair that with the cover letter generator only after the resume underneath passes a posting-specific scan.
When you need a clean base file, build your resume in a parser-friendly layout, then run the analytics loop on that export instead of a design-heavy template.
Resume check using data analytics to refine your CV: your next move
A resume check using data analytics to refine your CV turns guesswork into a short loop: scan, log gaps, edit one layer, re-scan the same posting, apply with a named file version. Recruiters still read for proof, but you stop losing roles before that read happens.
- Baseline formatting on your master file before you tailor keywords.
- Posting-specific scans for top targets with a simple tracker row per apply.
- Metric-heavy bullet swaps instead of summary stuffing when match is low.
Pick one role you want this week, run the free resume check, fix the first red flag on the list, and upload only after the second scan on the same description looks cleaner. That is how analytics stop being a score obsession and start getting you human eyes on the file.
Small logged edits compound across a job search batch faster than another full rewrite with no record of what changed.
Read more
Frequently asked questions
Track keyword match against the posting, formatting parse flags, and a before-and-after score from the same checker. Add one note on which bullet moved the needle. Re-run only after a deliberate edit, not after every typo fix.
Baseline once on your master file, then posting-specific checks for each top-five application. For batch applies to similar roles, one representative scan per family is enough if you log which file version went out.
No. Analytics surface gaps and formatting risks. You choose which bullets to swap and which metrics to add. The checker shows SQL is missing; you pick the project that proves SQL with a number attached.
There is no universal pass line. Strong match on required skills plus clean parsing beats a high generic score with wrong keywords. If match stays thin on a must-have, fix the file or skip the apply.
A simple sheet with role title, date checked, score, and file version works well. Columns for missing keywords and formatting flags help you spot repeat mistakes without rebuilding the whole CV each night.